// the blog
AI, ML & LLM notes
Deep-dives on AI engineering, machine learning, large language models and shipping code.
Notes from actually building this stuff — written by Muhammad Junaid, an AI engineer working on RAG systems, agents and GenAI products day to day. Posts here lean practical: what the retrieval and chunking choices really cost, where agent architectures fall over in production, and which trade-offs only show up once real users hit a system. If you want the plain-English explainers instead of the engineering write-ups, start with the AI guides.
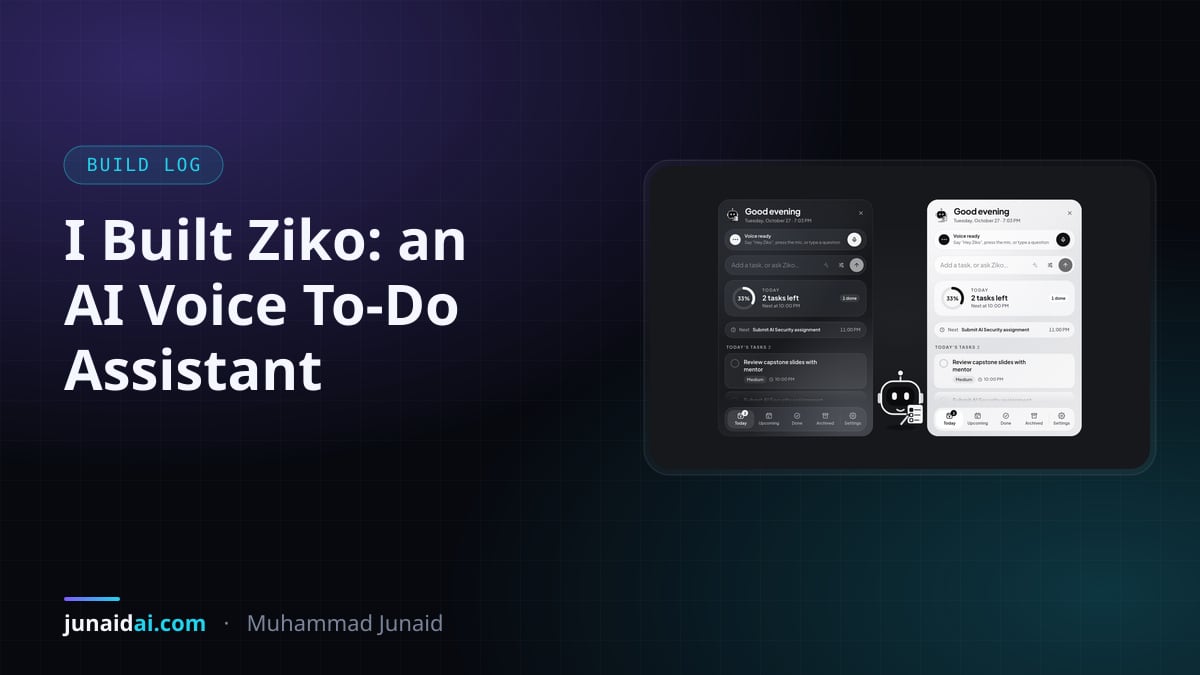
I Built Ziko, an AI Voice To-Do Assistant: What Gemini Live, Wake Words and Linux Taught Me
How I built Ziko, a desktop pet that runs my to-do list by voice: Gemini Live tool calls, an on-device wake word, reminders that fire once, and Linux fights.
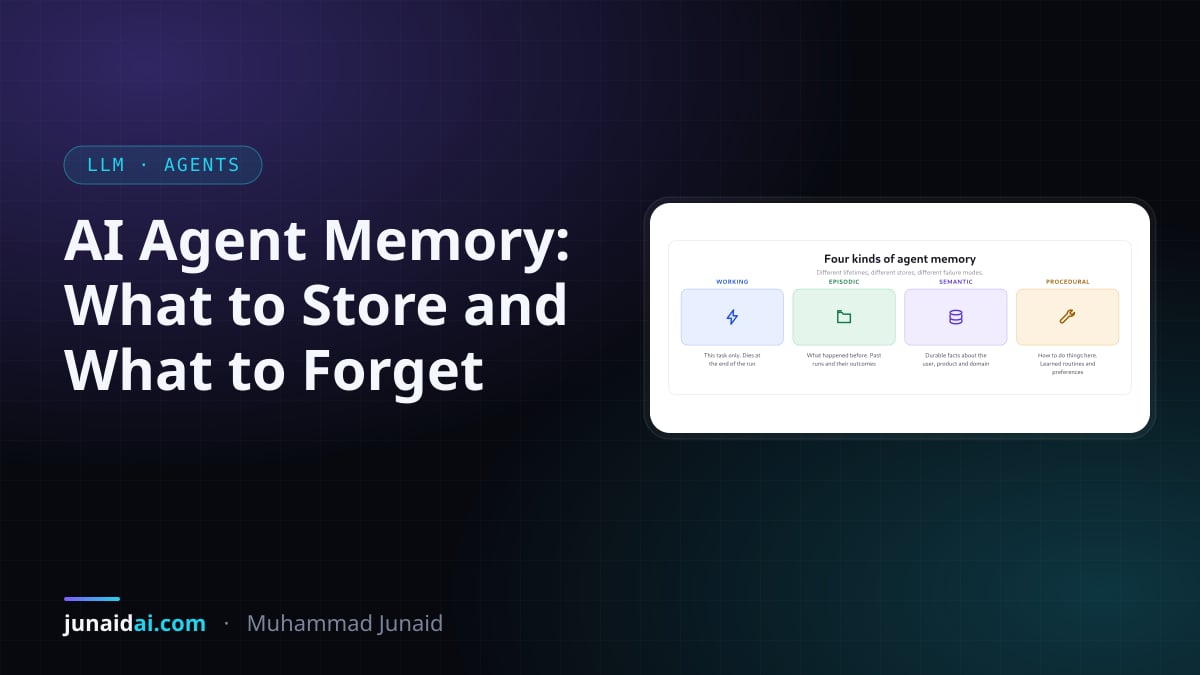
AI Agent Memory: What to Store, What to Forget, and Why the Write Path Matters
Agent memory is a real discipline now. The four types, why retrieval is the easy half, and how a naive memory system quietly poisons its own context.
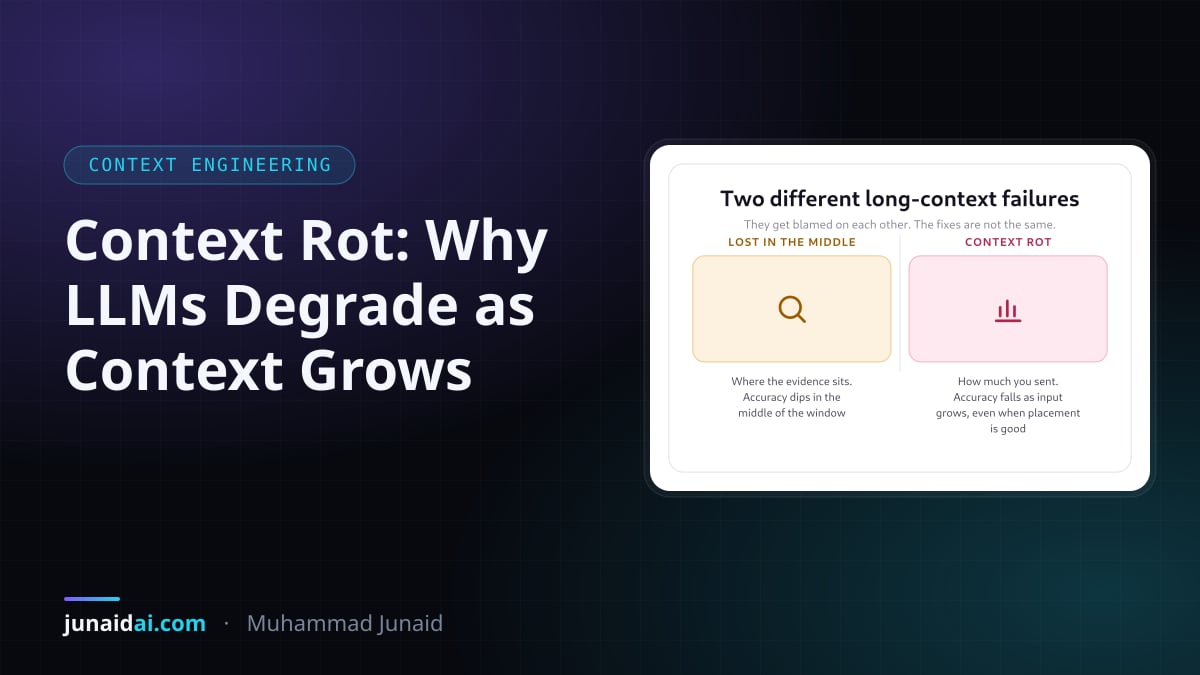
Context Rot: Why Your LLM Gets Worse the More You Give It
More tokens in, worse output out — even well inside the context window. What context rot is, how it differs from lost-in-the-middle, and how to fix it.
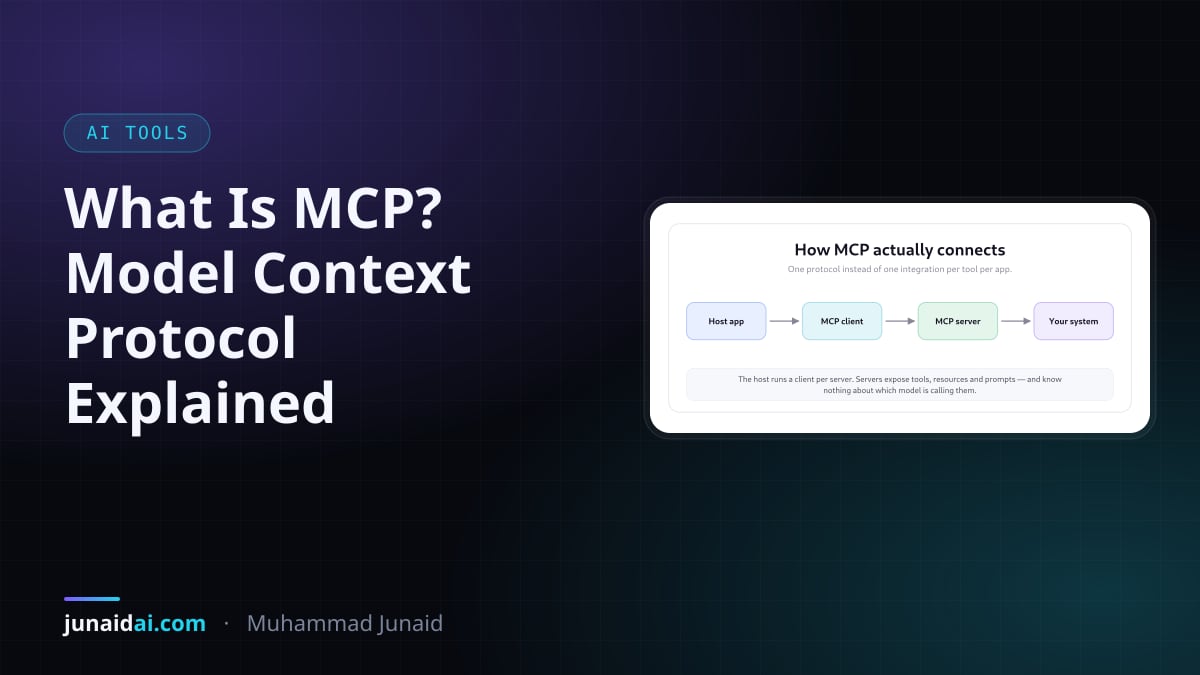
What Is MCP? The Model Context Protocol Explained for Developers
MCP is the USB-C port for AI tools — one protocol instead of one integration per app. How it works, what a server exposes, and where it still hurts.
Building a Production RAG Pipeline That Doesn't Hallucinate
A practical walkthrough of the retrieval, chunking, and grounding choices that separate a demo RAG app from one you can ship.